The next twenty-eight days just got a lot more interesting. A new public commitment promises either one visible product improvement per day, or a hard reset for everyone. The clock started this morning.
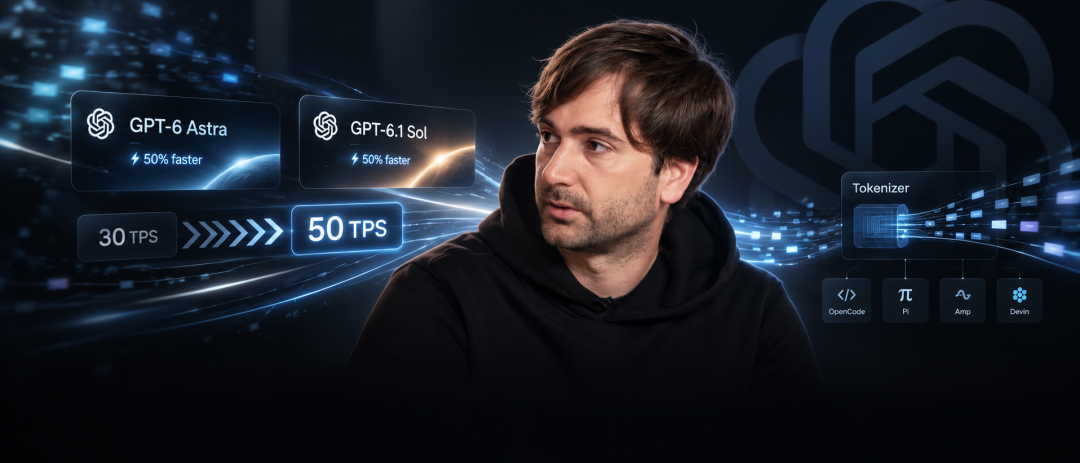
The first move targets the single thing that frustrates developers most: latency. GPT-6 Astra and GPT-6.1 Sol now default to a generation speed roughly 50% faster than before, jumping from a sluggish 30 tokens per second to around 50 TPS across every ChatGPT login surface — and, critically, every developer tool built on top of the same backend. Tools as varied as autonomous-coding agents, terminal workbenches, and workflow orchestrators all inherit the upgrade with no code change required.
The official explanation points to two things. First, raw concurrency and scheduling gains on the serving stack. Second — and more interesting — a substantially reworked tokenizer that compresses the token count required for the same task. Long code generation and multi-step reasoning both burn through fewer tokens per useful unit of output. The throughput win is partly an efficiency win.
Some early testers note that the headline number is most visible through API-tier traffic; consumer chat experiences vary more by region and load. The ceiling is real. The floor is uneven.
Claude's Subscription Value Is Now Five Times GPT-6.1
The same morning brought a second, less welcome finding. A widely-cited semiconductor and AI research outfit published a brutal real-world test: it purchased the highest-tier ChatGPT Pro and Claude Max subscriptions, drove them through long-horizon coding and agentic workloads until each hit its weekly ceiling, and converted the consumed compute into API-equivalent dollars.
At the $200/month tier, ChatGPT Pro used to deliver roughly $14,000 of API value. After the recent halving of included usage, that number collapses to about $2,084. Claude's Max 20x plan, by contrast, still produces about $11,726 of API value at the same $200/month price point. The gap is around 5.6x. At the $100 tier and the $20 tier, the ratio is essentially identical: roughly 5.4x and 5.6x in Claude's favour, respectively.
Side-by-side visualisations of the resulting bills have circulated widely: one subscription is being eaten by usage, the other is delivering serious compute for the price. The contrast is hard to ignore.
Why the Gap Is So Large
The economics are revealing when you look under the hood. Anthropic's mid-tier plans reach break-even once a customer uses around 20% of the included quota. OpenAI's plans, by contrast, start losing money once utilisation passes roughly 11.4%. The headline subscription price is, in effect, a hedge: most users will not come close to the included quota, so the company comes out ahead.
That hedge worked fine when "usage" meant chat. A few thousand tokens in, a few thousand out. The arithmetic breaks once agentic coding becomes normal. A single autonomous workflow — read a repository, plan a change, write a patch, run the tests, iterate — can burn a thousand times more tokens than a back-and-forth conversation. Customers who previously never came close to their limit suddenly sail past it.
The recent decision to cut ChatGPT Pro's included quota in half is the logical, if painful, response. The plan was subsidising heavy users out of light ones. The reset tries to rebalance the equation.
The Super App Convergence
Speed and pricing grab the headlines, but the more strategic move is structural. The current product roadmap is converging four product lines — Chat, Work, Codex, and Dots — into a single interface, organised around what the user wants done rather than which tool they happen to be in.
The visible changes are revealing. The model picker is being hidden. The intermediate reasoning trace is being hidden. Customers will not pick a model or count how many steps the system took; they will describe a goal and wait for a result. Every text the system produces will carry an invisible watermark identifying it as AI-generated, a quiet concession to the content-authenticity debate. The chat and work modes are merging. Dots' capabilities will fold in, reaching a billion-plus users inside the main app.
Advertising is also coming — initially in image-generation queues, where idle wait time is real. The shift marks a willingness to trade some user-experience purity for unit economics at scale.
What It Means for Builders and Buyers
For developers, the speed bump is unambiguously good. 50 TPS is fast enough that autocomplete feels like autocomplete, not a slow typewriter. The new tokenizer means lower bills for high-volume workloads even before any model improvement.
For buyers of agentic coding capacity, however, the calculus has changed. A subscription that looked like a bargain at $200/month now demands a careful look at usage patterns. Heavy users will need to either move down to API pricing, move up to higher tiers, or genuinely shop around. The reported gap with Claude's plans is large enough that the comparison is no longer academic.
For the broader market, the episode crystallises a point that was previously theoretical. Tokens per dollar — not tokens per second — is the metric that decides who wins the agentic era. Inference speed matters for feel. Pricing efficiency decides who can afford to run a real workload.
Day 1 delivered throughput. Days 2 through 28 are where the harder questions will be answered.
Why This Matters Beyond the Subscription Chart
The speed-up, the pricing reset, and the product-line convergence are three separate decisions that happen to land on the same day. Read together, they describe the new shape of competition at the frontier.
First, the user experience is being deliberately flattened. When the model picker disappears and the reasoning trace disappears, the buyer is no longer choosing between abstract capability rankings. They are choosing between outcomes. That shift favours whoever can deliver a complete, dependable answer regardless of which model produced it — and disadvantages the buyer who wants to optimise the system by hand.
Second, the watermark decision is the most consequential quiet policy of the release. Every text output from ChatGPT or Codex will carry an invisible mark identifying it as AI-generated. For enterprise customers worried about provenance, this is welcome infrastructure. For users hoping to pass AI text off as human work, it is a sharp warning. The same product now serves both masters, and tells them different things.
Third, advertising inside an image-generation queue is the first revenue line outside subscriptions. It is a small surface today. It is also a proof of concept: the consumer AI app can sustain itself on something other than monthly fees. The strategic implication is that future price cuts may not require future fundraising rounds to subsidise them.
The 28-day clock is, in effect, an opening bid. Throughput is the easy win, the one the engineering team could ship in a single release. The harder wins — pricing sustainability, agentic-economics parity with the leading competitor, a credible super-app story — are what the next four weeks will be watched for.